Piko
 Explore prompt ↗
ChatGPT
IllustrationChatGPT
Japanese style heartwarming four panel comic prompt
Creator @derek_wall90176
Prompt
Generate a set of four-panel Japanese-style heartwarming comics, clean hand-drawn anime line art style, warm rice-brown and light brown monochromatic tones, soft cream-colored background, simple soft shadows, overall warm and healing atmosphere. Aspect ratio: Square 1:1, standard 2x2 four-panel layout, each panel separated by thin brown borders. Top title: Large text "夫婦の日", with a small heart on each side, handwritten-feel dark brown.

[Four-panel content]
Panel 1: Standing portrait of a young Asian couple. The man stands behind the woman, hands gently placed on her shoulders, both smiling at the camera.
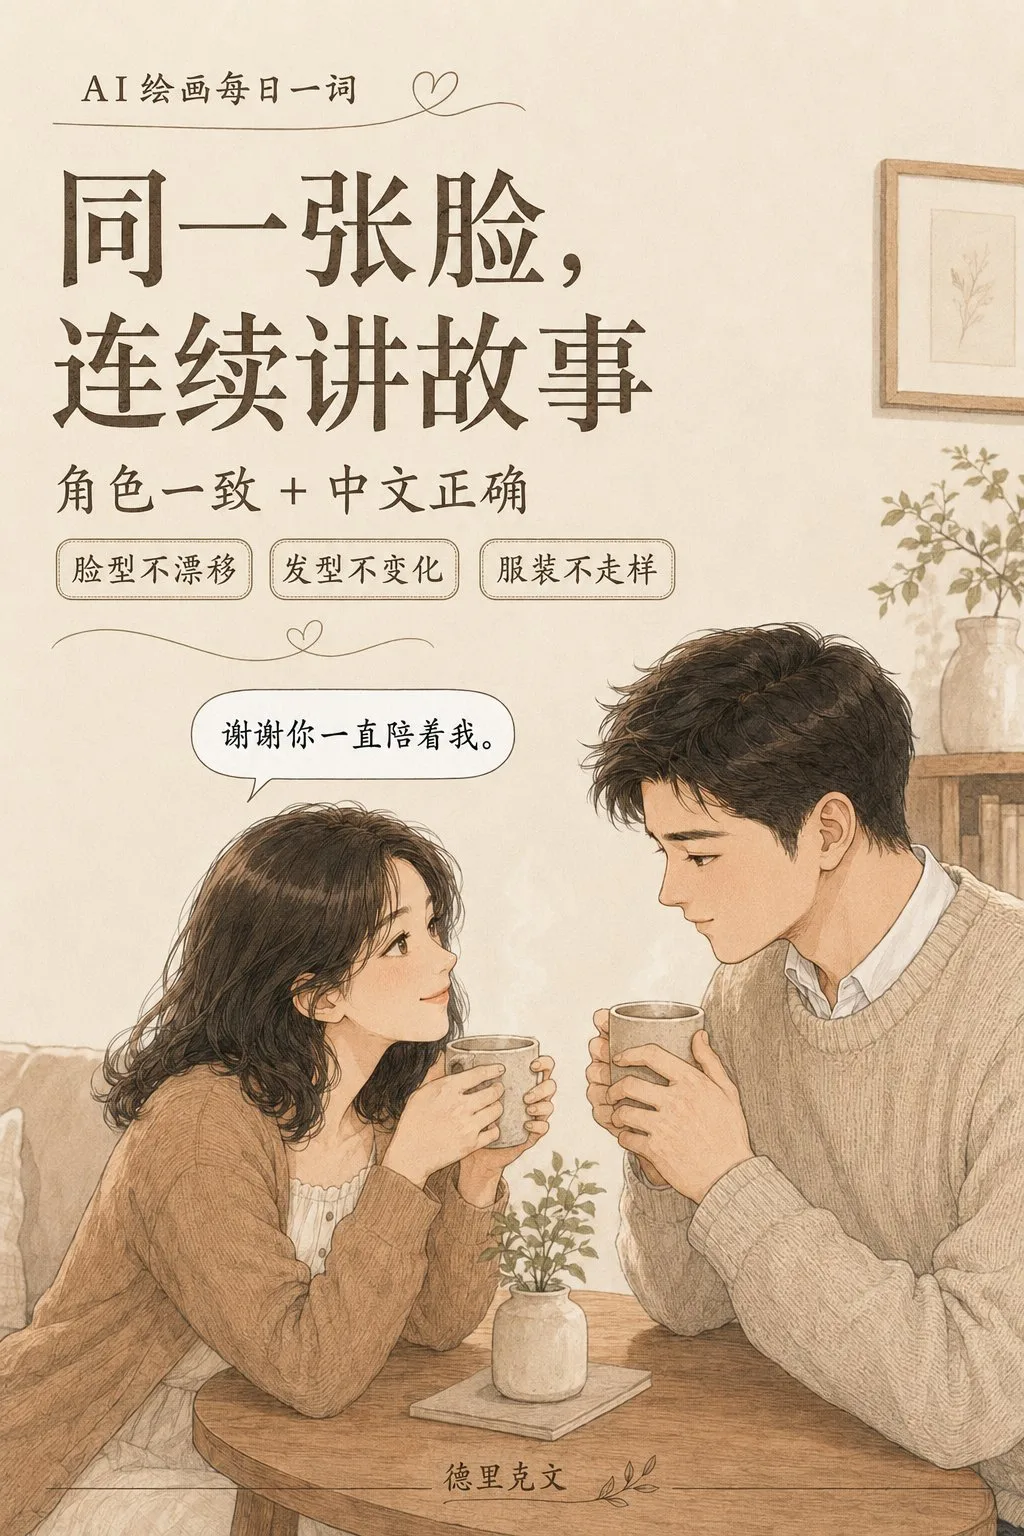
Panel 2: The couple sitting in a cozy interior, holding mugs with both hands, looking at each other and smiling. The woman's speech bubble clearly writes in Chinese: "谢谢你一直陪着我。" White rounded speech bubble, clear black text.
Panel 3: The couple cooking together in the kitchen. Both standing side-by-side in front of the stove, the man stirring, the woman helping, expressions focused and happy.
Panel 4: The couple hugging tightly. The man bows his head to gently kiss the woman's forehead, the woman closes her eyes and smiles.

[Character consistency mandatory requirements]
The two characters must maintain exactly the same face, same hairstyle, same clothing, and same body proportions from Panel 1 to Panel 4. Any drift is prohibited.
Man: Short hair, gentle appearance, wearing a simple sweater or shirt.
Woman: Medium-long hair, gentle appearance, wearing home-style clothes.

[Style and texture]
Clean hand-drawn anime line art, monochromatic warm rice-brown + light brown + cream white, simple shadows, like Japanese life comics or healing-style illustrations.

[Text requirements]
The Chinese in the speech bubble must be correct, clear, no garbled characters, no distortion. Avoid: realistic photography, 3D rendering, vibrant colors, complex backgrounds, character face collapse, garbled text, cheap sticker feel. Core logic: cross-image character consistency + zero Chinese garbled characters = finally able to tell a story stably.
Copy the text, add your own details, and try it in your image model.