Piko
 Explore prompt ↗
ChatGPT
PhotographyChatGPT
Cinematic photography tutorial character consistency layout
Creator @GrayNoteLab
Prompt
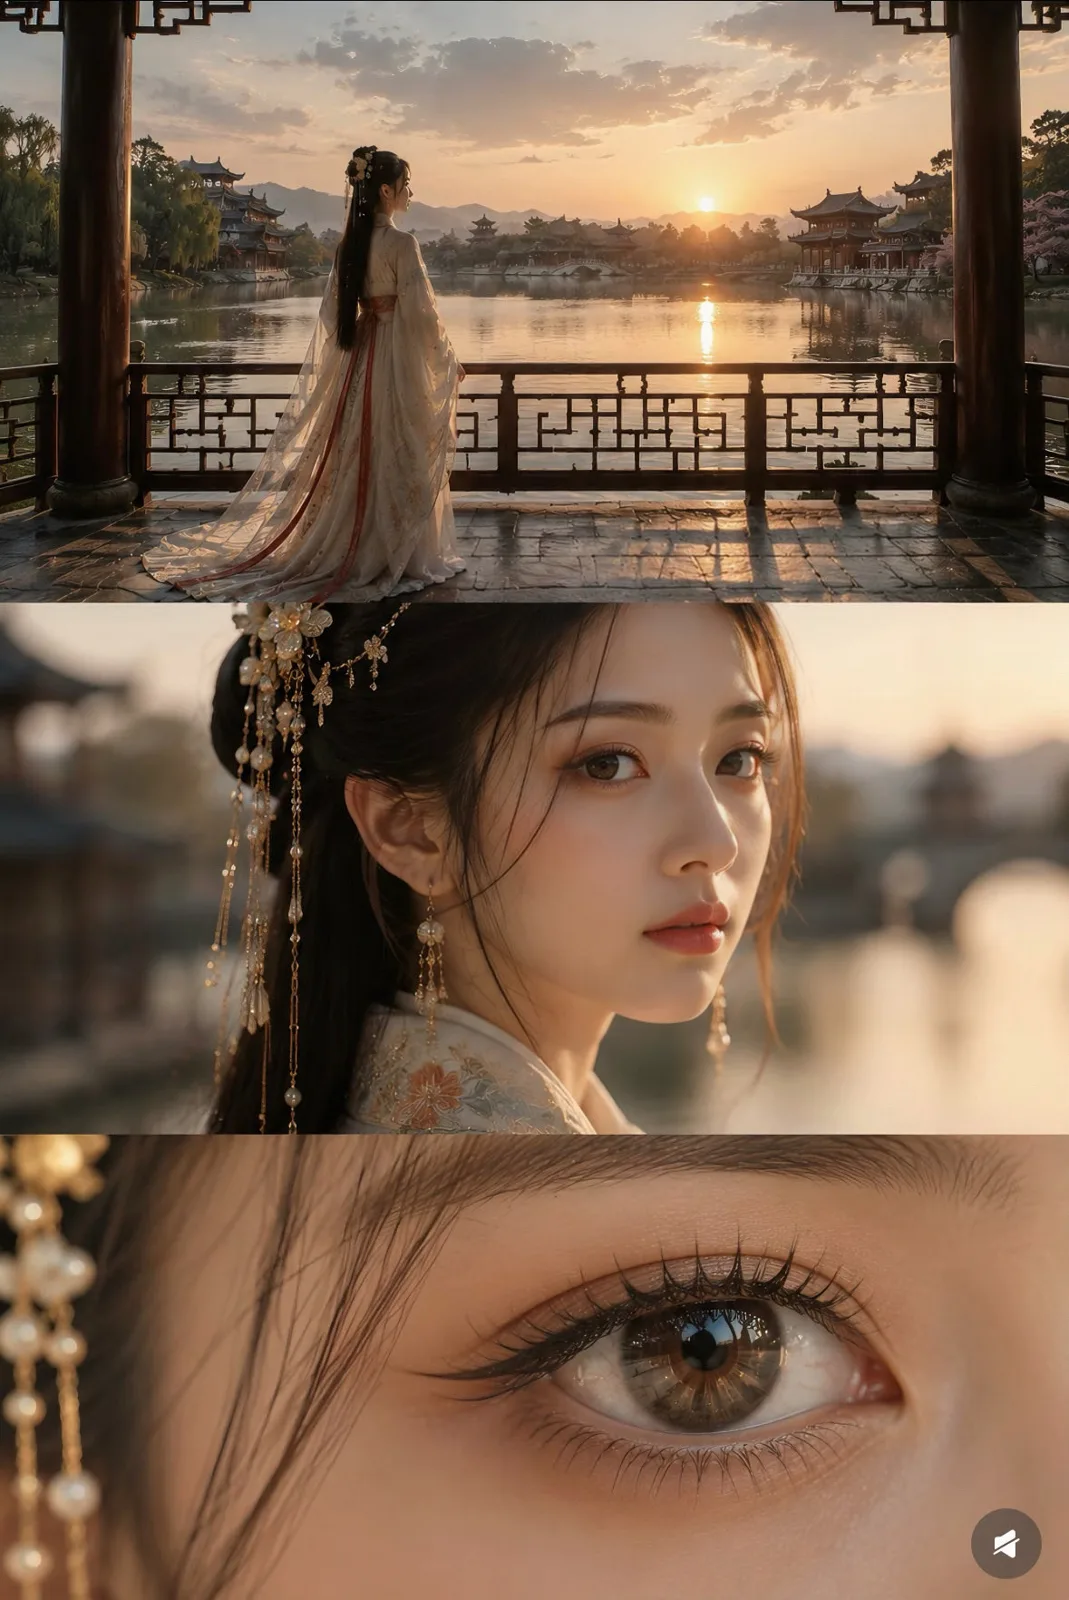
A cinematic photography teaching layout, vertical three-grid, displaying three shot types of the same character from top to bottom, maintaining 100% character consistency (same face, same hairstyle, same makeup, same clothing, same accessories), ultra-realistic cinematic texture, 8K, HDR, high detail, film-grade lighting.
First image (Long Shot)
Wide-angle 24mm, full body in frame, character standing in the center of an ancient palace courtyard, occupying about 15%-20% of the frame, focusing on the relationship between architecture, sky, environment and character, cinematic composition, symmetrical composition, epic atmosphere, golden hour light and shadow.
Second image (Close-up)
85mm cinematic lens, head and shoulders close-up, character occupying 70%-80% of the frame, background naturally blurred, highlighting facial expression, hair accessories, clothing embroidery, skin texture and eyes, maintaining the exact same character identity as the first image.
Third image (Extreme Close-up)
100mm Macro lens, filming only the same single eye, occupying more than 90% of the frame, only retaining the eyebrows, eyelashes, eyelids, iris, and corner of the eye, no full nose, mouth, or the other eye, no facial misalignment, no double eyes, no deformation, no redundant facial features. Iris texture, eyeball highlights, eyelashes, and skin pores are all realistically visible, character remains completely consistent with the second image.
The three images are arranged vertically, unified tone, unified lighting, unified character, unified film-grade color grading, ultra-high definition, no noise, no artifacts, no AI flaws, no distortion, no repeated facial features, no eye misalignment, no low quality.
Copy the text, add your own details, and try it in your image model.